

Every month, the Chocolate Milk Cult reaches over a million Builders, Investors, Policy Makers, Leaders, and more. If you’d like to meet other members of our community, please fill out this contact form here (I will never sell your data nor will I make intros w/o your explicit permission)- https://forms.gle/Pi1pGLuS1FmzXoLr6
Databricks paid $1.3 billion for MosaicML. Harvey raised $550 million at a $15.5 billion valuation. Gartner expects the specialized AI model market to reach $4.9 billion in 2026.
Several multi-billion dollar Silicon Valley backed companies are trying to sell you a similar philosophy: Your company has unique data. General AI doesn’t know that data. If you spend a fortune training on your own data, you can get much better returns compared to generic models.
Once you get into this cope, every road leads to becoming a training-cel. Have more data? Train more. Your information changes? Train again. The model still makes mistakes? Clearly, it needs more training. There is a loss function Shangri La after which all your business problems a prompt away from completion, and you should give joyfully give your AI Cloud providers all your operating margins to reach this happy ending.
However, there is a slight issue here… once you start getting into the details, a growing body of research suggests that training language models on proprietary knowledge is probably the most inefficient way to make that knowledge useful.
Now here you might stop and ask me about the impressive benchmark results. And how it makes intuitive sense that a model trained on the specific data/workflows will outperform general models. This is where we’re going to split training into two different outcomes —
Training to teach a model new facts is very expensive and mostly doesn’t work. We will go deep into the science of learning by exploring what pre-training, post-training, and continual learning can (and can’t) teach a model — and how much each approach will cost you.
Training to teach a model workflows (for eg how to navigate a filesystem to perform a certain task) is more grounded in science, but still doesn’t have the ROI that AI companies pretend it does.
Most importantly, I will show you with evidence how so many of the companies peddling this nonsense skip over the fact that many of the impressive improvements attributed to training can also come from building better reasoning, retrieval, memory and data infrastructure surrounding the model with more reliability and safety and at a much lower cost.
Now these are big claims, and I’m challenging some industry “best” practices (best for the investors and companies, for sure). I also understand that the people who peddle the post-training myth often struggle with reading the soo many big words that are found in research papers (which is why they are still peddling beliefs from the BERT era of LLMs). So in the spirit of good science and true intellectual inclusivity (literacy should not be a barrier to public participation), I am issuing a simple open challenge to anyone claiming the superiority of specialized training and can’t back it up by pointing to third party research (which doesn’t exist):
Use a real baseline. Compare your trained system against a capable model with proper reasoning, retrieval, memory, and tools. Beating a naked base model proves very little.
Show us your harness and evidence. Publish enough of your architecture, evaluations, and results to establish that training — not a weaker baseline — is responsible for the improvement.
Prove the economics. Compare the full cost of training against investing the same resources in better inference infrastructure. Include engineers, failed experiments, inference, refreshes, and vendor fees. Which investment delivers more?
Beat our general-purpose reasoning engine. We’ll compare your domain-trained system against Irys’s domain-agnostic reasoning infrastructure (you can sign up for a free Irys account in minutes, so there’s no setup complexity there; API also available) on identical inputs, with the same evaluation and transparent costs. Let’s see us what your specialization actually adds.
Join me as we do a Ateba Gautier level fraud-check on one of the most hyped trends in AI right now.
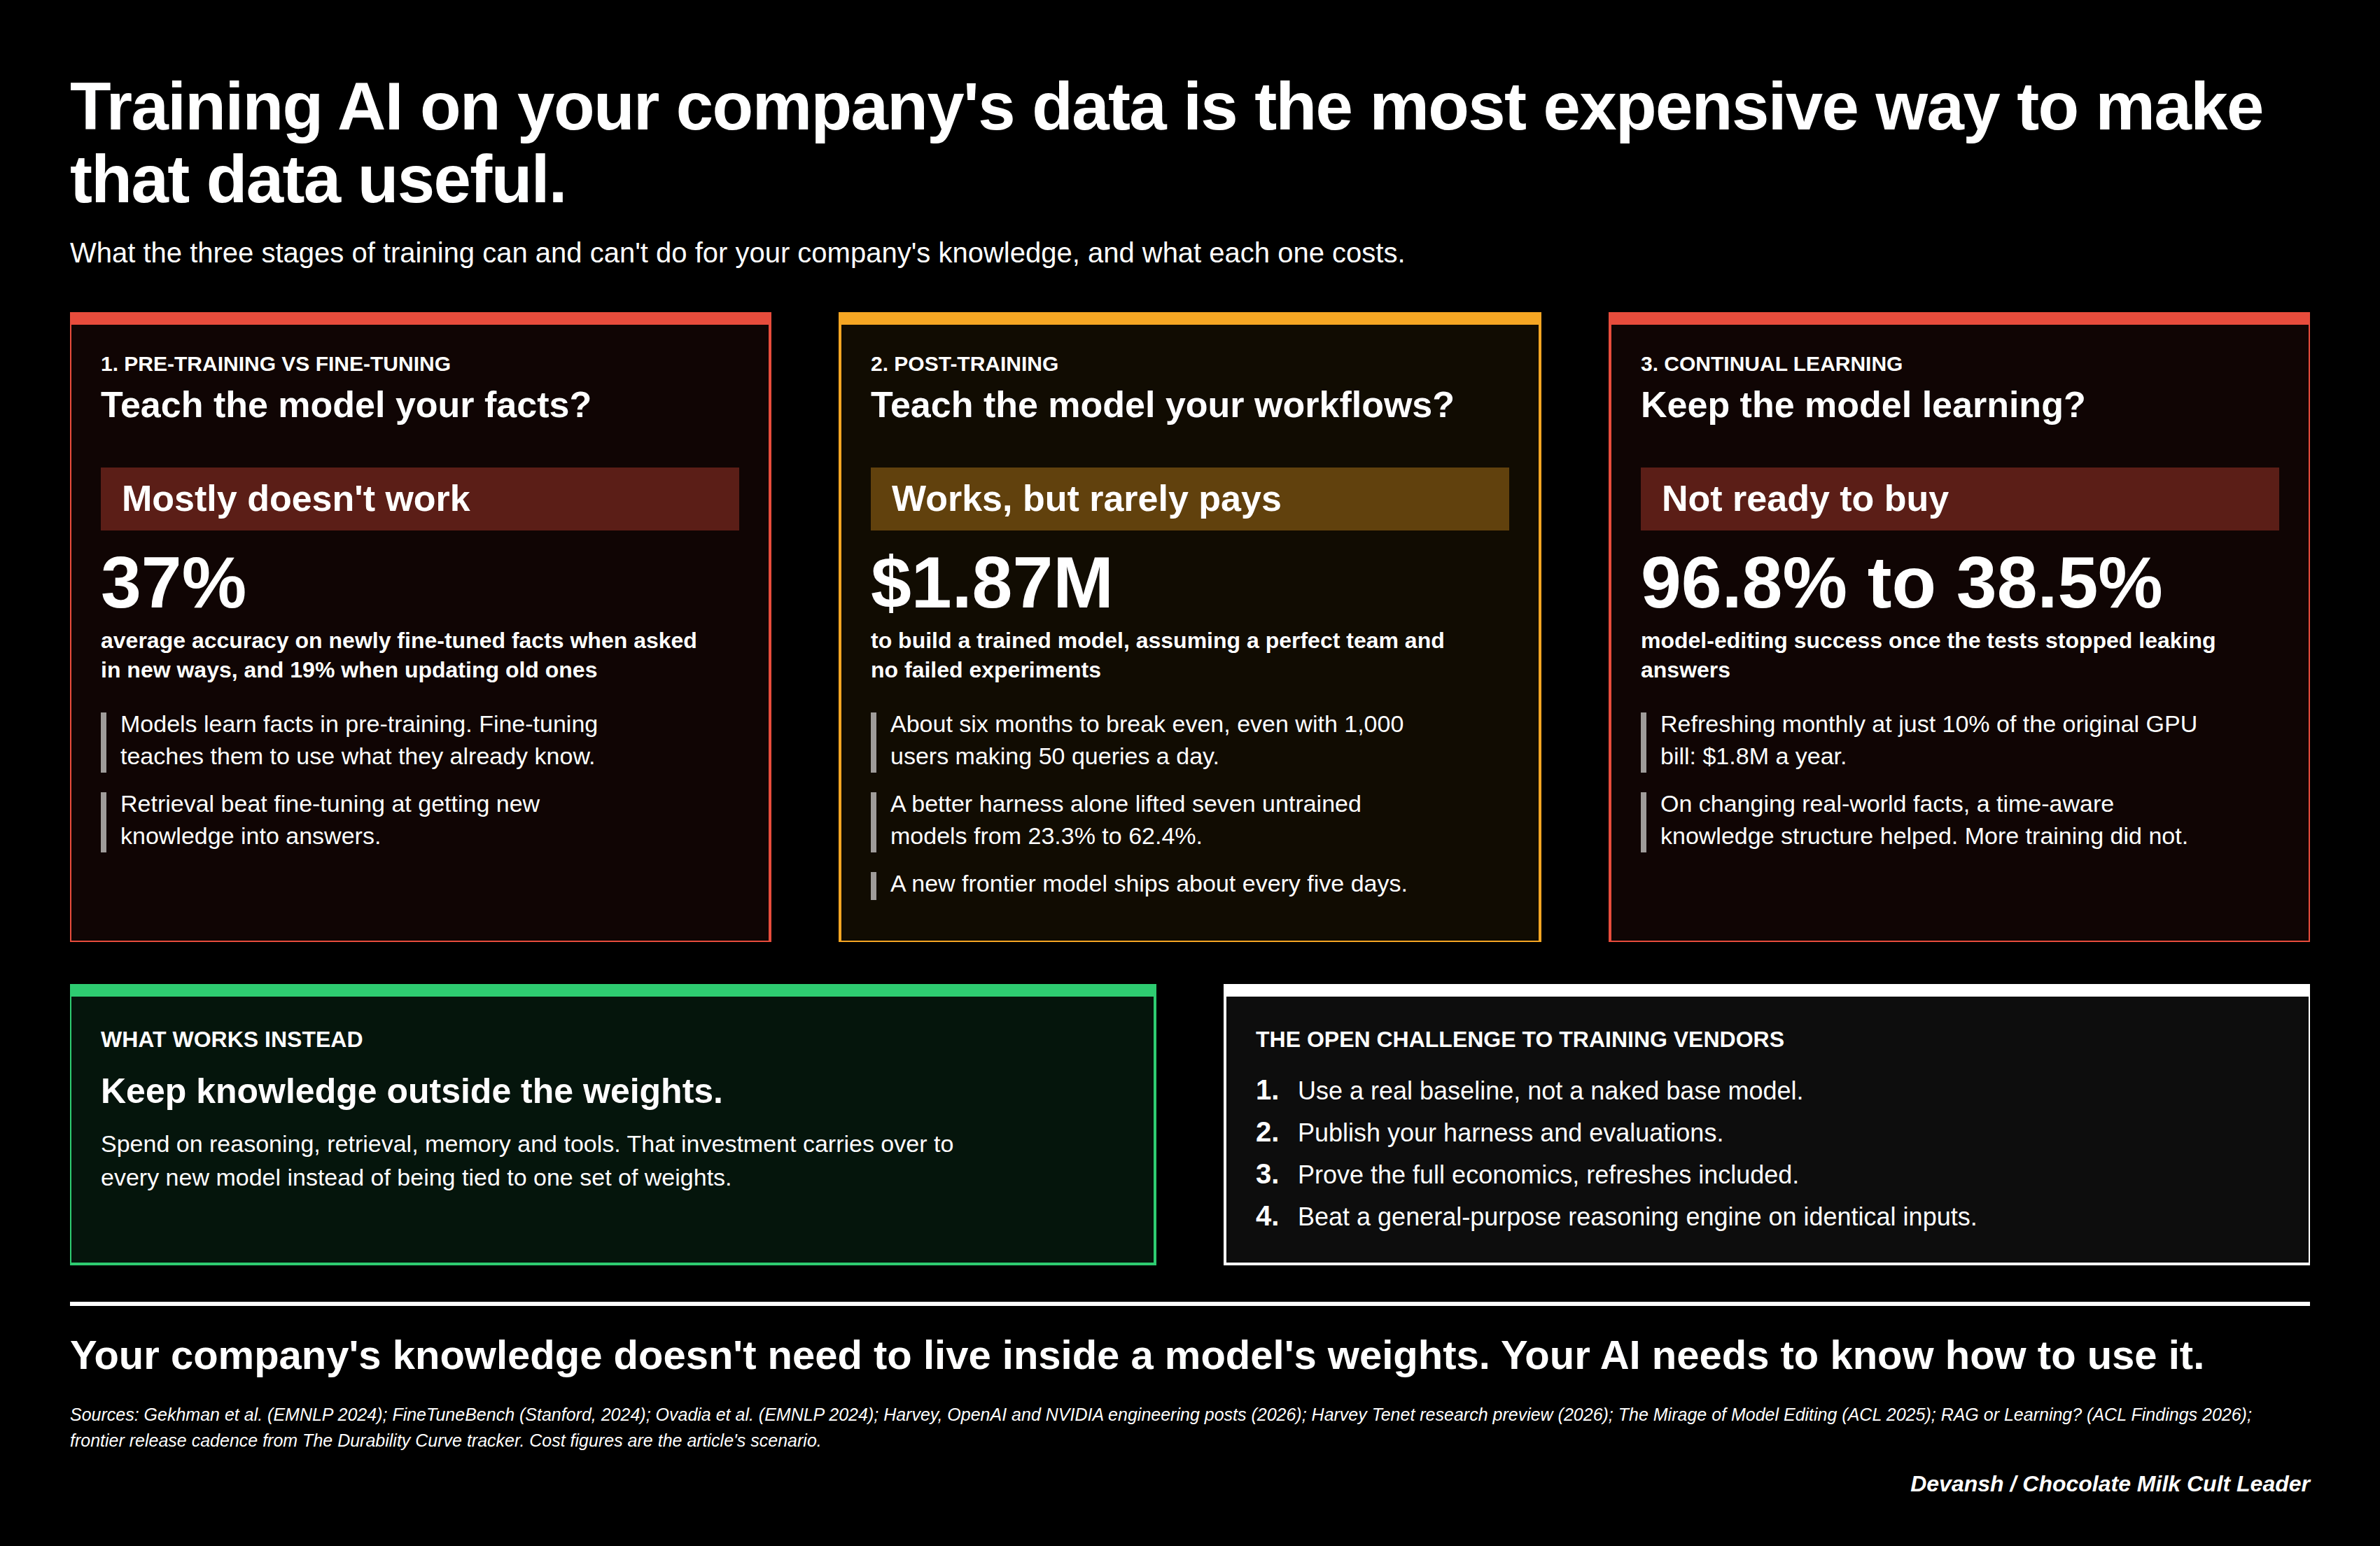
Executive Highlights (TL;DR)
Pre-training is where models learn most of their factual knowledge. However this is extremely expensive, which is why most vendors use the language of pretraining (“train on your own data”, “models that remember your facts”) but in reality try to sell post training.
However, post-training is much better at teaching behaviors than reliably injecting new facts. So the mechanism they’re trying to sell doesn’t actually meet do what their marketing departments promise. While not the focus of this article, this is also why companies like Hippocratic AI, which imply that they have special ways to train domain specialized LLMs, are misleading customers. There just is no way to reliably inject knowledge in the weights of already trained LLMs.
This is clear when we look at the benchmark marketing. Vendors show impressive gains from training, but these amazing numbrs are often compared against weak baselines or unreproducable reasoning infrastructure. The latter is especially important when you consider that multiple bits of research have shown us that you can get really impressive results by improving the harness, w/ no investments in model training required.
This means that for most people investing in your own training pipeline (even the relatively cheaper post training) doesn’t manifest much ROI. This is especially true for systems that draft a lot (environments where files are changed constantly, tool specs are rebuilt etc). This drift is increasingly common with agentic systems (which tend to change a lot of things), hence we have seen the rise of continual learning. However…
Continual learning doesn’t magically solve the problem. Your knowledge, software, and workflows keep changing. Training-dependent improvements need ongoing updates and testing. Better retrieval, memory, and reasoning infrastructure can instead be reused across successive generations of models.
All in all, most of the conversation around training your models is smokes and mirrors that is meant for headlines but has almost no merit in actual research and products.
Hey there. I keep this newsletter ad-free, w/o sponsors, and mostly w/o paywalls to ensure that everyone has access to high-quality deep-dives on the most important ideas in the AI Industry without any bias. B/w my research, independent verification, and the chocolate milk needed to produce these works, these deep-dives take a lot of time, resources, and infrastructure. For just 10 USD/month or 100 USD/year, you can help me continue my vision of democratizing access to the most important ideas in AI by becoming a paid subscriber over here —

PS — Supporting this work doesn’t have to come out of your pocket. If you read this as part of your professional development, you can use this email template to request reimbursement for your subscription.
Want access to a repository containing all of our research? 300+ files containing our notes of various experiments, discussions with cutting-edge teams, and insights into where the industry is headed next. Get a Founding Member Subscription to AI Made Simple. Want to talk to me for details/get my insights into the tech ecosystem? Reach out to me through any of my socials over here or reply to this email.
1. Pre-training: Where AI actually learns its knowledge
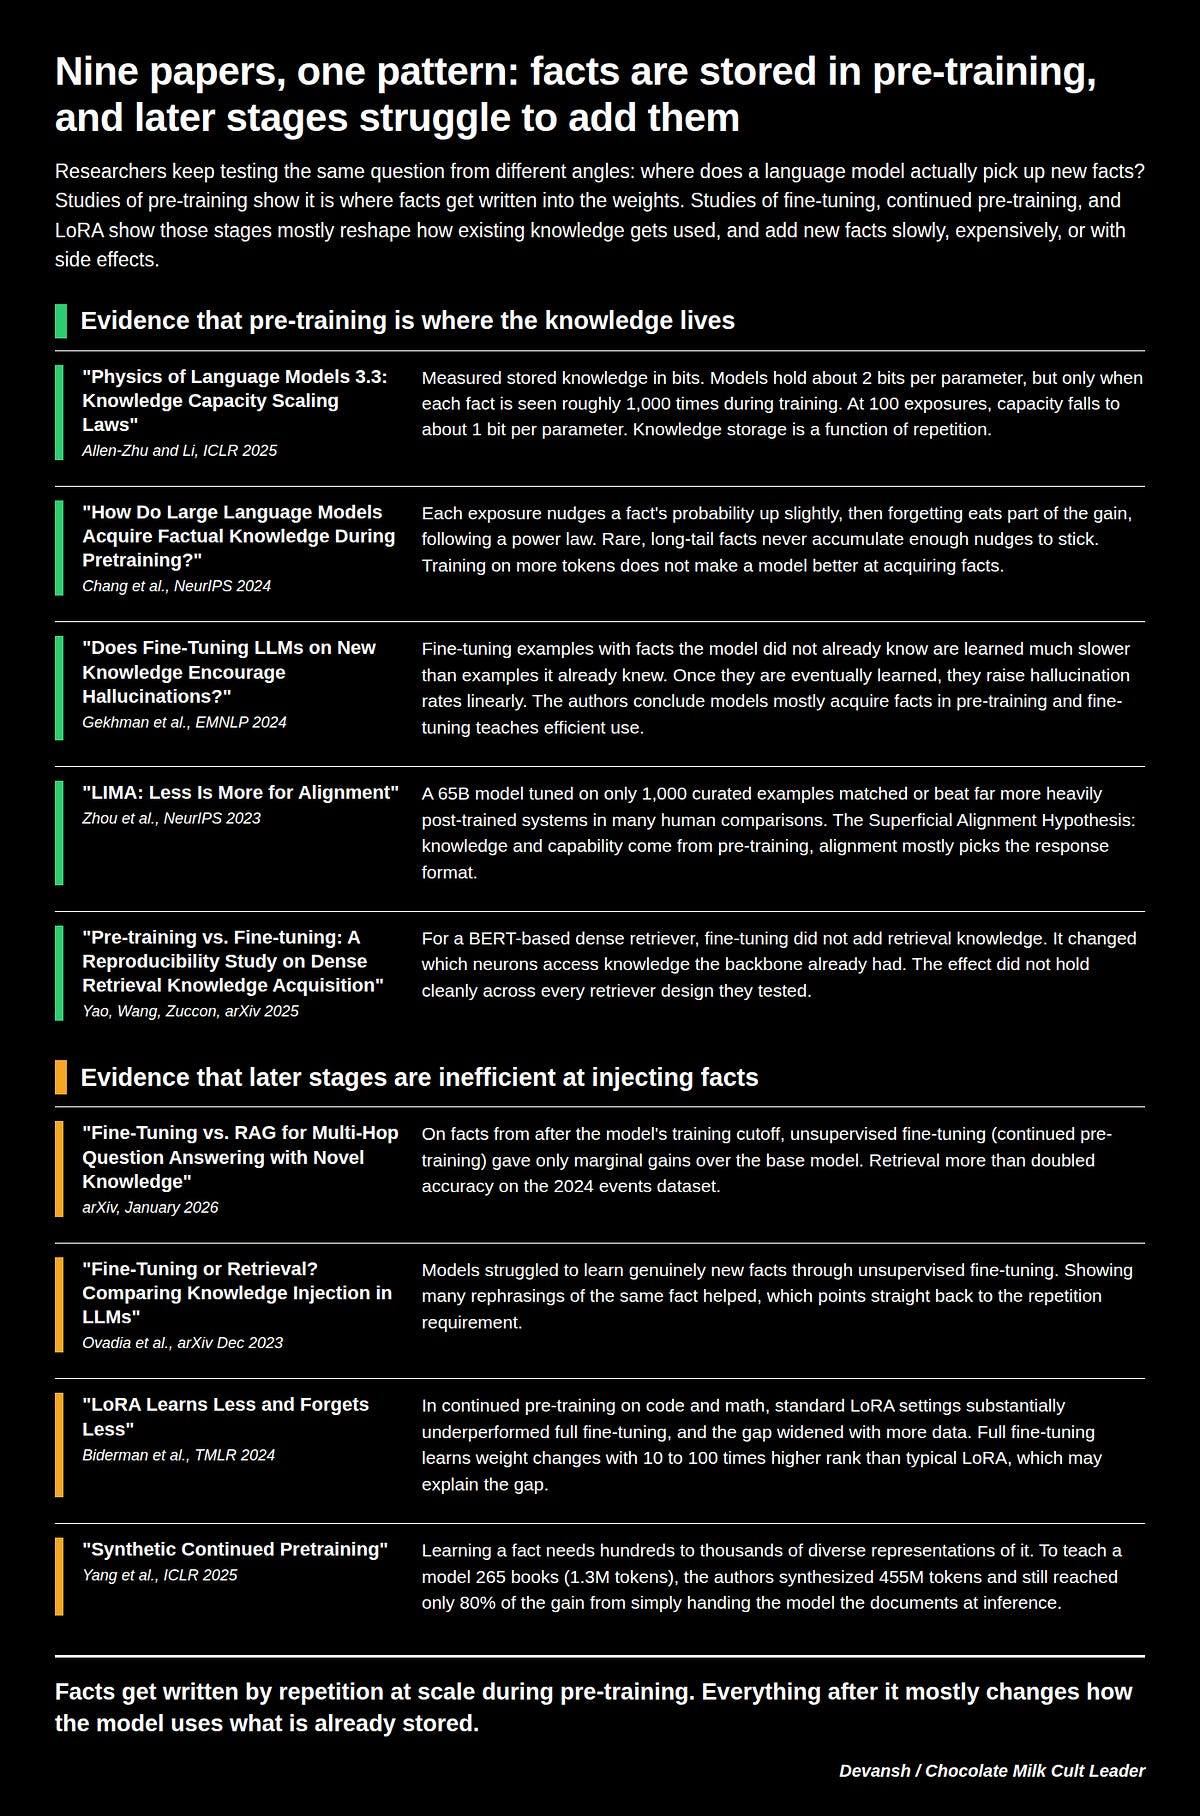
We’ll keep this section short, because almost nobody seriously recommends that enterprises train their own foundation models from scratch. But ironically enough, most people are ignorant of the fact that if your goal is to teach a model new facts and associations, pre-training is where most of that learning actually happens. This was shown quite conclusively studying Gekhman et al. (EMNLP 2024) reached an even more interesting conclusion:
“large language models mostly acquire factual knowledge through pre-training, whereas fine-tuning teaches them to use it more efficiently.”
(In case you’re skeptical of forming your worldview on the basis of one research paper, I’ve complied a list of papers that will help you really understand the knwoledge acquisition process in language models —)
Unfortunately, training a foundation model from scratch requires enormous amounts of data, computing power, and specialized expertise. This is why new pretrains are relatively rare, and most model releases tend to work on taking the knowledge base and utilizing it better through post training. To their credit, even Harvey and the other “custom train” data companies are not stupid enough to tell you that you need to post train the data.
This leads us to what they do sell you. In a nutshell, their proposition can be summarized as following
Take an existing model
Train it on your company’s data (either directly on the documents/procedures so it “learns your company data” or indirectly by learning to mimic your workflows/the right behaviors.
Tehee.
????
Endless Money Machine, no more expensive employees.
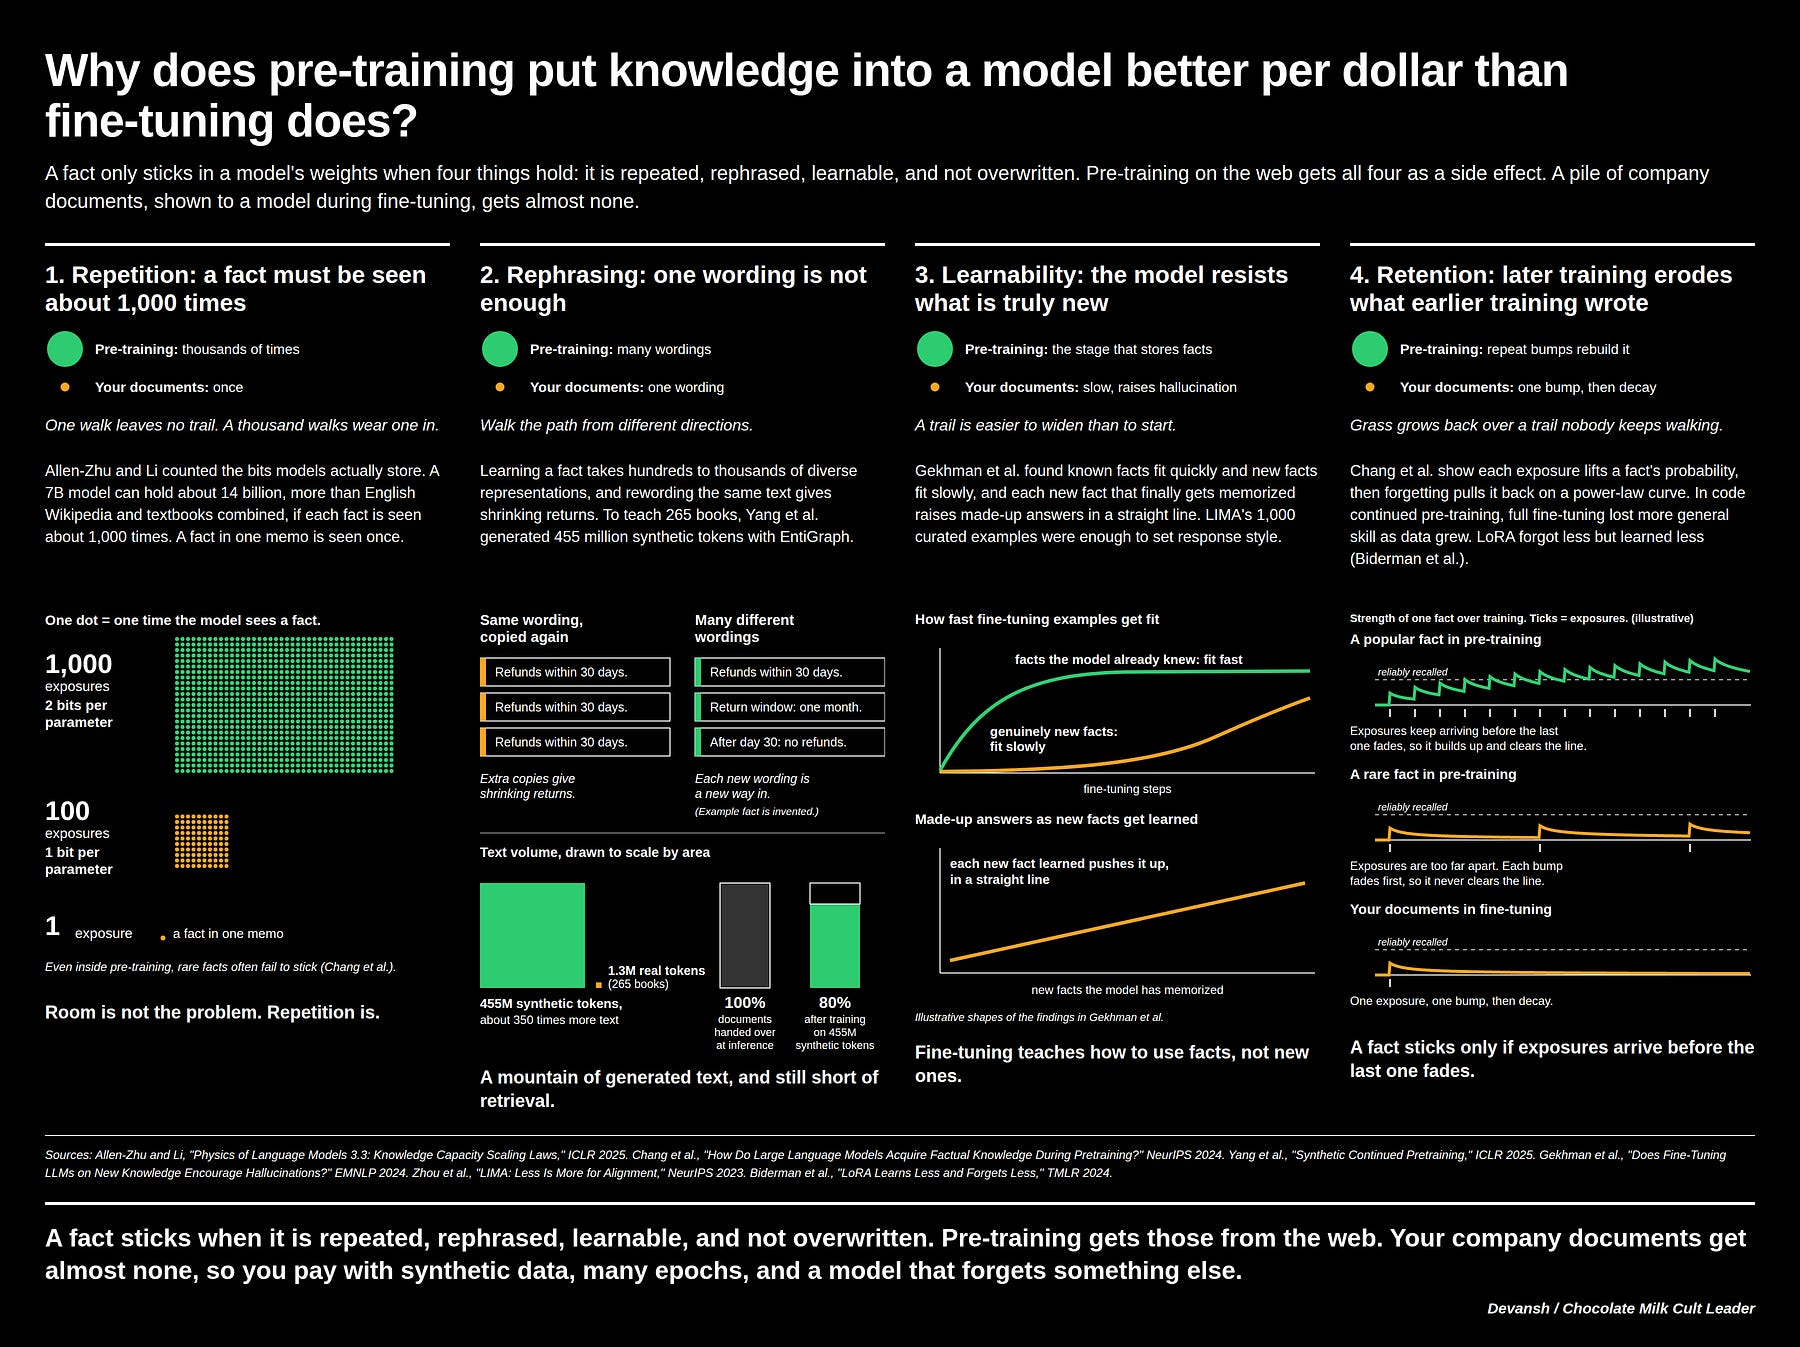
Sounds much cheaper. But does it actually work? Pitch 1 (train on data) does not (cue the reasearch list mentioned earlier about why pretraining is the only real place to inject knowledge, or refer to the image below for a more distilled understanding of why post training/later stages are hostile to knowledge acquisition).
What about the second one? Can you leverage the fact that post training can be used to teach models behaviors to best teach an AI system how to work within your corporate environment? Technically yes, but let’s see why this approach still makes no sense.
FineTuneBench, a Stanford study examining commercial fine-tuning services in 2024, found that models achieved just 37% average generalization accuracy when learning new facts, and 19% when updating existing knowledge. In other words, even when models learned their training examples, they struggled to apply that information to questions they hadn’t seen before. Another study, Ovadia et al. (EMNLP 2024), directly compared teaching models factual knowledge through unsupervised fine-tuning versus giving them access to the relevant information through retrieval. Retrieval consistently won in their experiments.
2. Why Post-training (very) is Overrated
Training models to follow specialized workflows can produce impressive results. The problem is that theres a huge difference b/w saying something can boost your performance and that something is the best (or even a good/economical) way to spend your resources. Let’s take Engram’s collaboration with Harvey. They trained an agent on 108 million tokens of synthetic law-firm data, improving closed-book factual accuracy from 4.7% to 72.6%. Their systems also hit inference costs of $0.13 per query versus $1.32 for Claude Opus 4.8.
Very cool, and it makes sense why this announcement was paraded heavily on social media. But let’s start digging into the details a little bit more. Firstly, we must note that their complete system also combined structured notes, search, and agentic execution. This immediately leads to the question — how much of the useful performance came from training, and how much came from the system surrounding the model? What did the training cost? Could a better reasoning system have achieved comparable results without it?
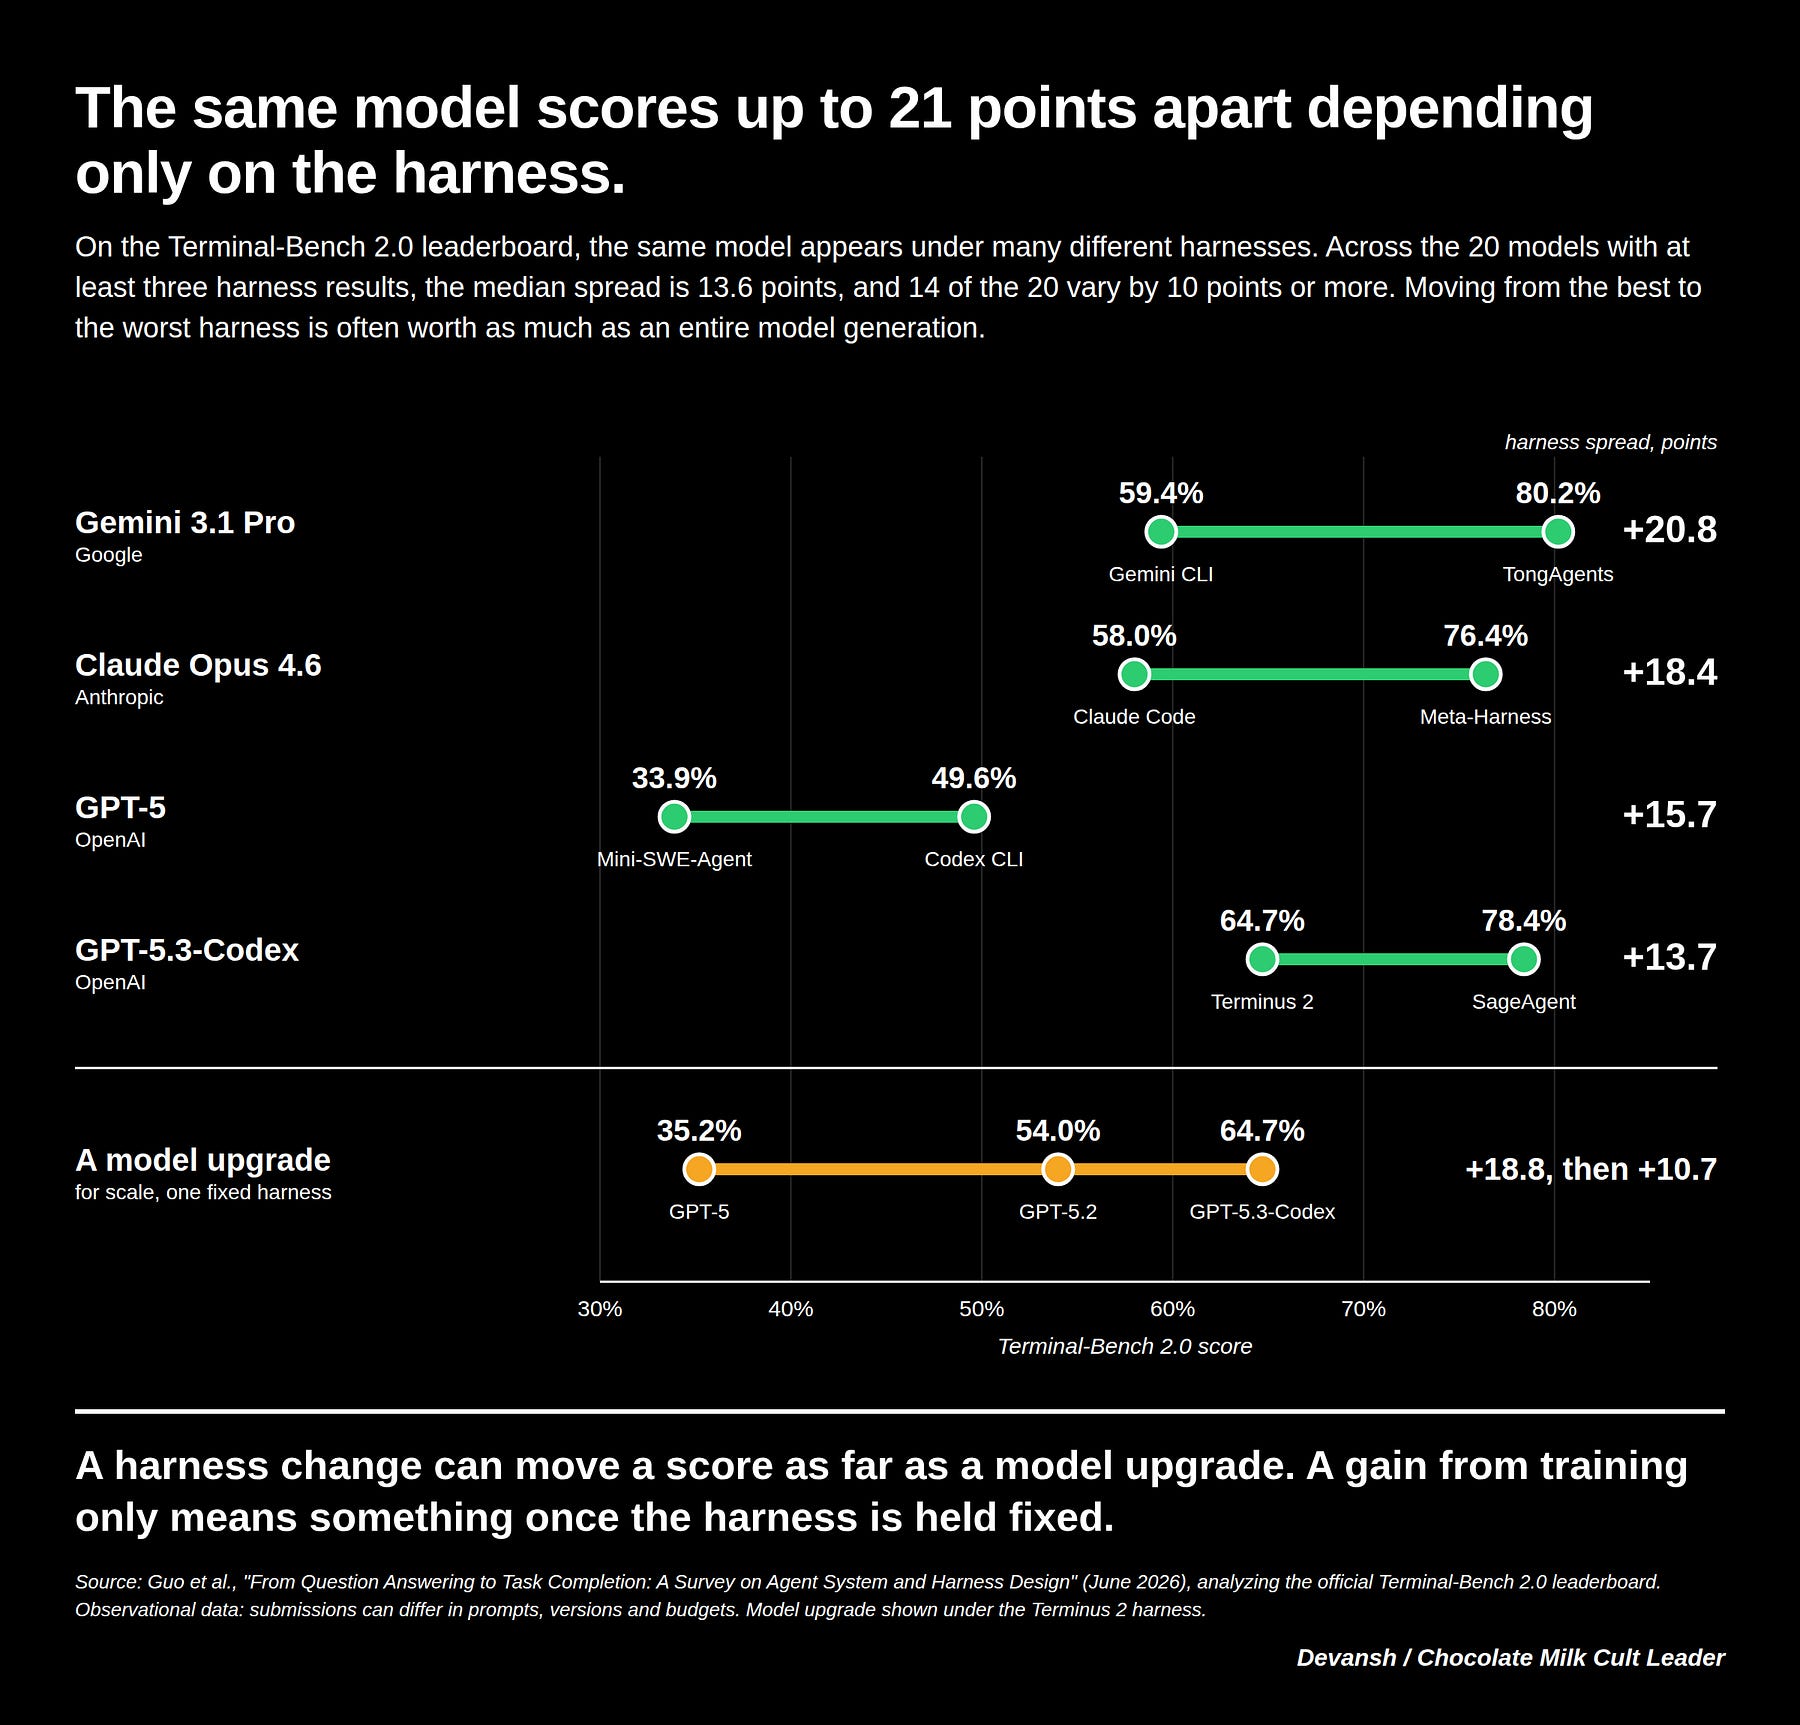
This is a recurring problem with the vendor benchmarks used to justify their specialized training: Companies either compare their trained models against relatively bare base models, or publish results using proprietary harnesses that we can’t properly inspect. There’s no way for us to know whether the harnesses where the post trained models follow good engineering practices, or if it’s vibe coded slop.
You might think I’m being nitpicky here, but comparing against multiple simple reproducible baselines is the very basis of scientific research. Without them, the publications parading around all the amazing results are just research cosplay, a kind of 0 nutrition junk food science science.
Let’s go one layer deeper than the lack of baselines. When we contextualize the training discussions within the larger AI ecosystem, one thing to note is that we consistently see no additional model training:
Harvey improved average criteria pass rates from 23.3% to 62.4% across seven models simply by replacing its standard harness with a recursive reasoning architecture.
OpenAI improved ARC-AGI-3 scores from 13.3% to 38.3% by changing two inference settings, while reducing output tokens sixfold.
NVIDIA improved agent correctness scores from 46 to 87 by adding verified skills, without retraining the underlying models.
Our own general-purpose reasoning infrastructure (stateful swarms) got really good results on the public Harvey LAB and the DELTA benchmarks without domain-specific training using an out of the box Gemini 3.7 Flash (non thinking mode), simply by using the base model much better.
Similarly, our fractal embeddings research demonstrated how improving the structure of information representations can improve performance without training proprietary knowledge into a foundation model. When it was independenlty implemented by Rob Currie, former CTO of the UCSC Genomics Institute, he found that it “works well improving accuracy over the original embeddings while learning a hierarchical structure based on biology.” The system even outperformed the Genentech baseline, even though it wasn’t designed or tested on the domain when we released it(Robs replication can be found here).
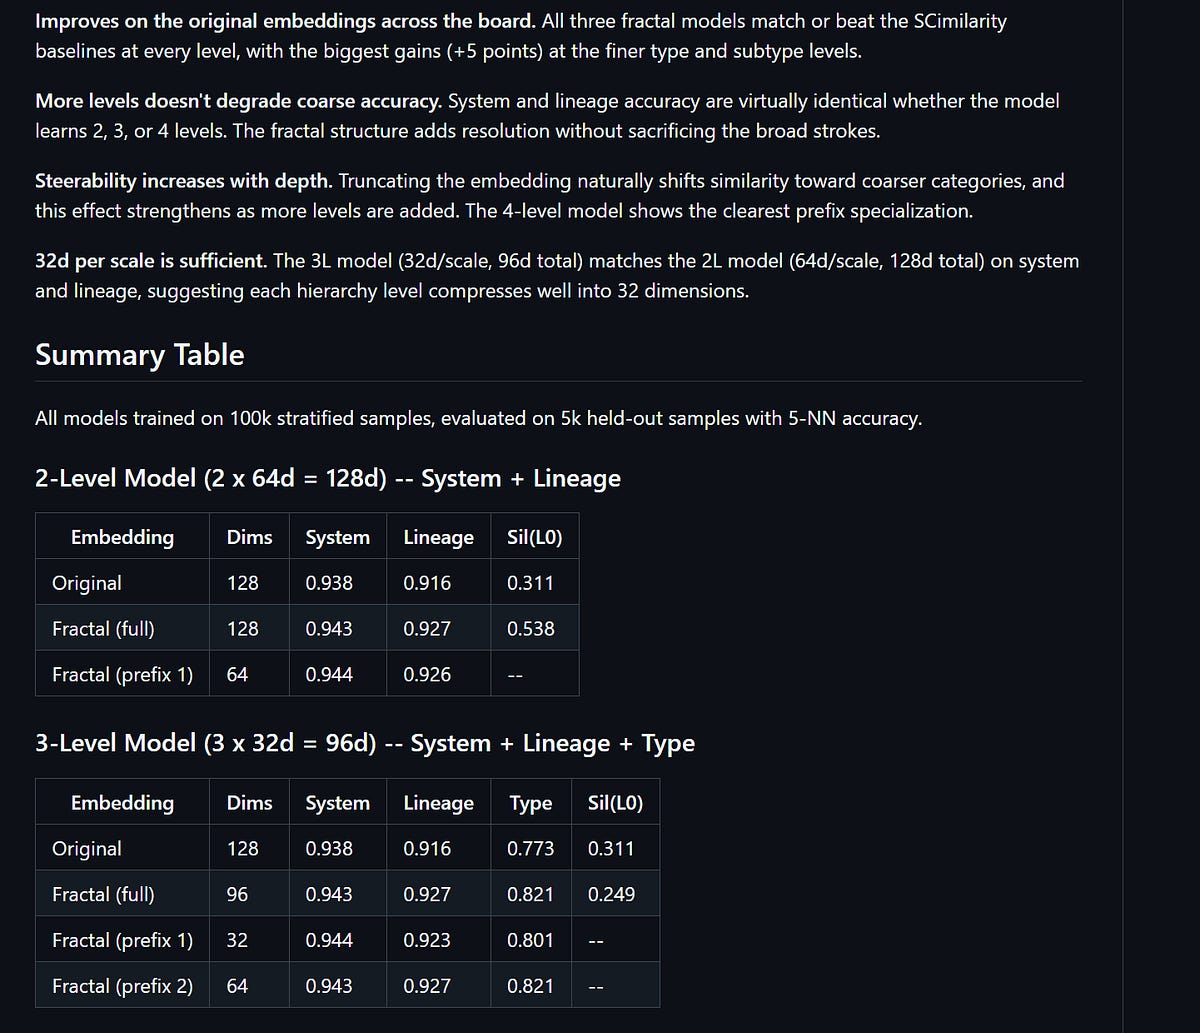
All that to say, there is a strong, and constantly growing field of research that clearly shows us that we can hit enormous improvements by making better use of models we already have. Why are we spending millions retraining them before exhausting these alternatives?
But fuck it, let’s for the sake of argument assume that your infrastructure is perfect. You’ve optimized your retrieval, memory, reasoning, and agentic execution. There’s absolutely nothing left to improve. You now want to squeeze out the remaining performance by training your own specialist model.
I don’t think you realize how much that costs, so let me show in a apinful amount of detail. Harvey Tenet was developed using approximately 150 NVIDIA B300 GPUs over two months. Renting that amount of compute continuously at roughly $7 per GPU-hour comes to about $1.5 million. Let’s take that as our baseline.
To train your new model, you’ll need a few people. Let’s build a pretty lean engineering team: two AI researchers at $250K each, two data engineers at $200K each, a model-training engineer at $240K, and an MLOps engineer at $220K. That’s $1.36 million in annual personnel costs. Add another $120K for evaluations, security, and supporting operations.
Assuming that you have a cracked team that needs only three months to 0–1 the whole thing, you’re looking at a bill of $370K on top of the training compute.
This brings your number to $1.87 million. To stay here, you’re making a few giant assumptions —
You’ve one shot hired the perfect team and not had to pay any costs in recruitment (standard industry fees are 20–30% that we’re cutting out; + the time required to hire but double your actual time requirements).
Every experiment works so you can get the perfect design without failures.
You’re completely overlooking the opportunity costs of putting all this effort and resources.
To amp up your savings, let’s say you’re willing to fire everyone in your perfect team after model deployment and keep just your training and MLOps engineers, with $60K annually for evaluations and monitoring. That’s another $520K a year.
So w/ these assumptions, how efficient is this decision? Assuming that your firm is filled with a 1000 power users making 50 queries daily and if your newly trained system is 0.50 cents cheaper/query, that gets you $25,000 in daily savings.
While that sounds impressive, that means you’ll need roughly 80 days after deployment to break even. Add the three months spent developing the system, and you’re approaching six months before recovering your investment.
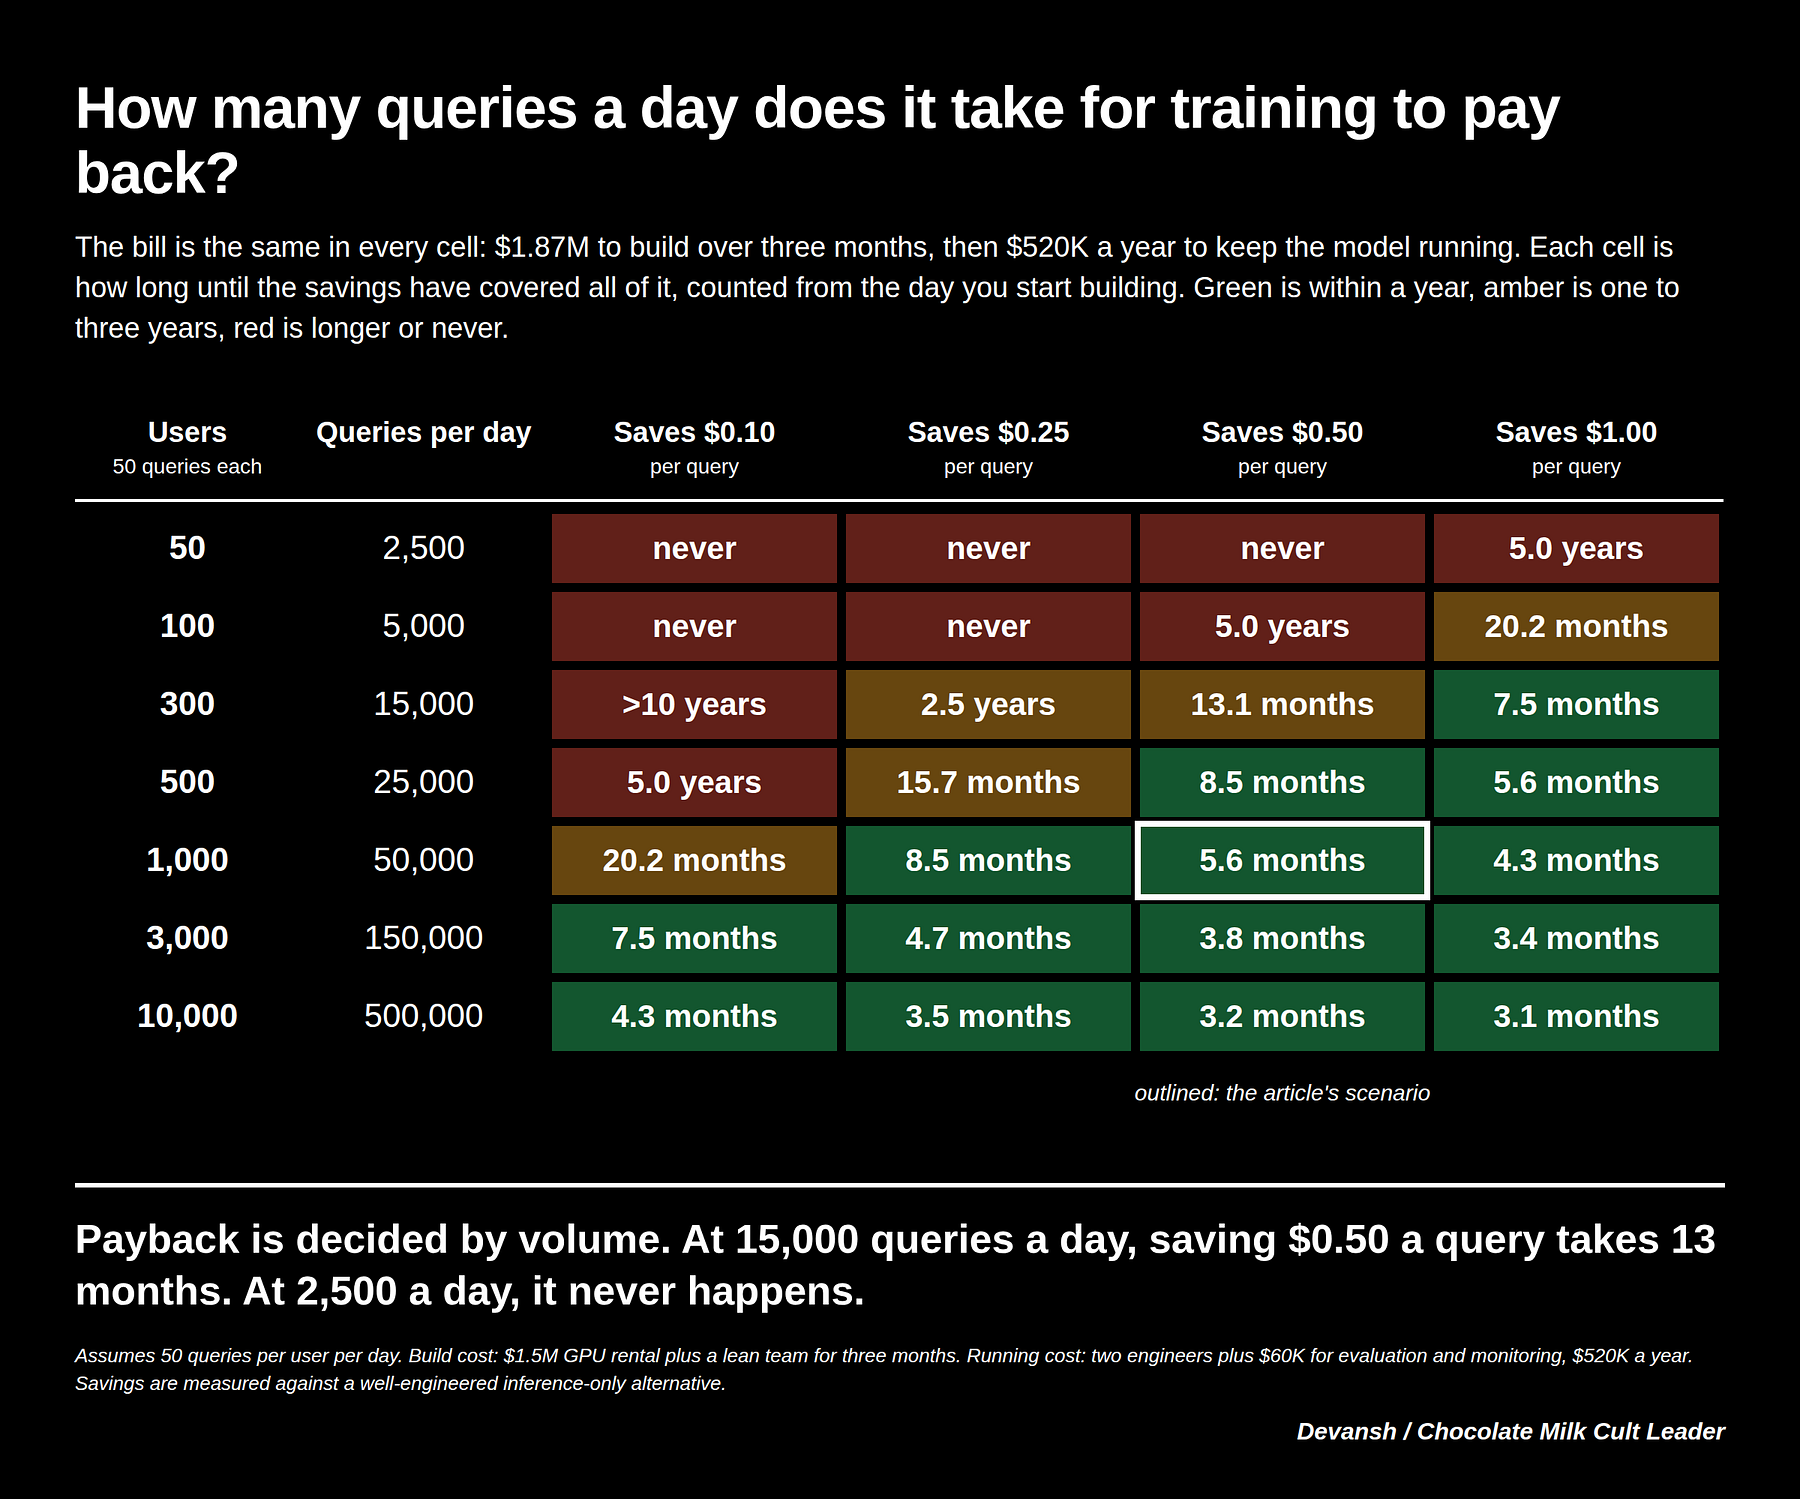
And remember, this is a fantasy scenario. You have 1,000 active users from day one, making 50 queries every single day, including weekends. Every team-member is hyper-competent (but somehow still not accpeting millions from foundation model labs or through their own startup), no experiments fail, and all the other operational wiggles are completely non-existent.
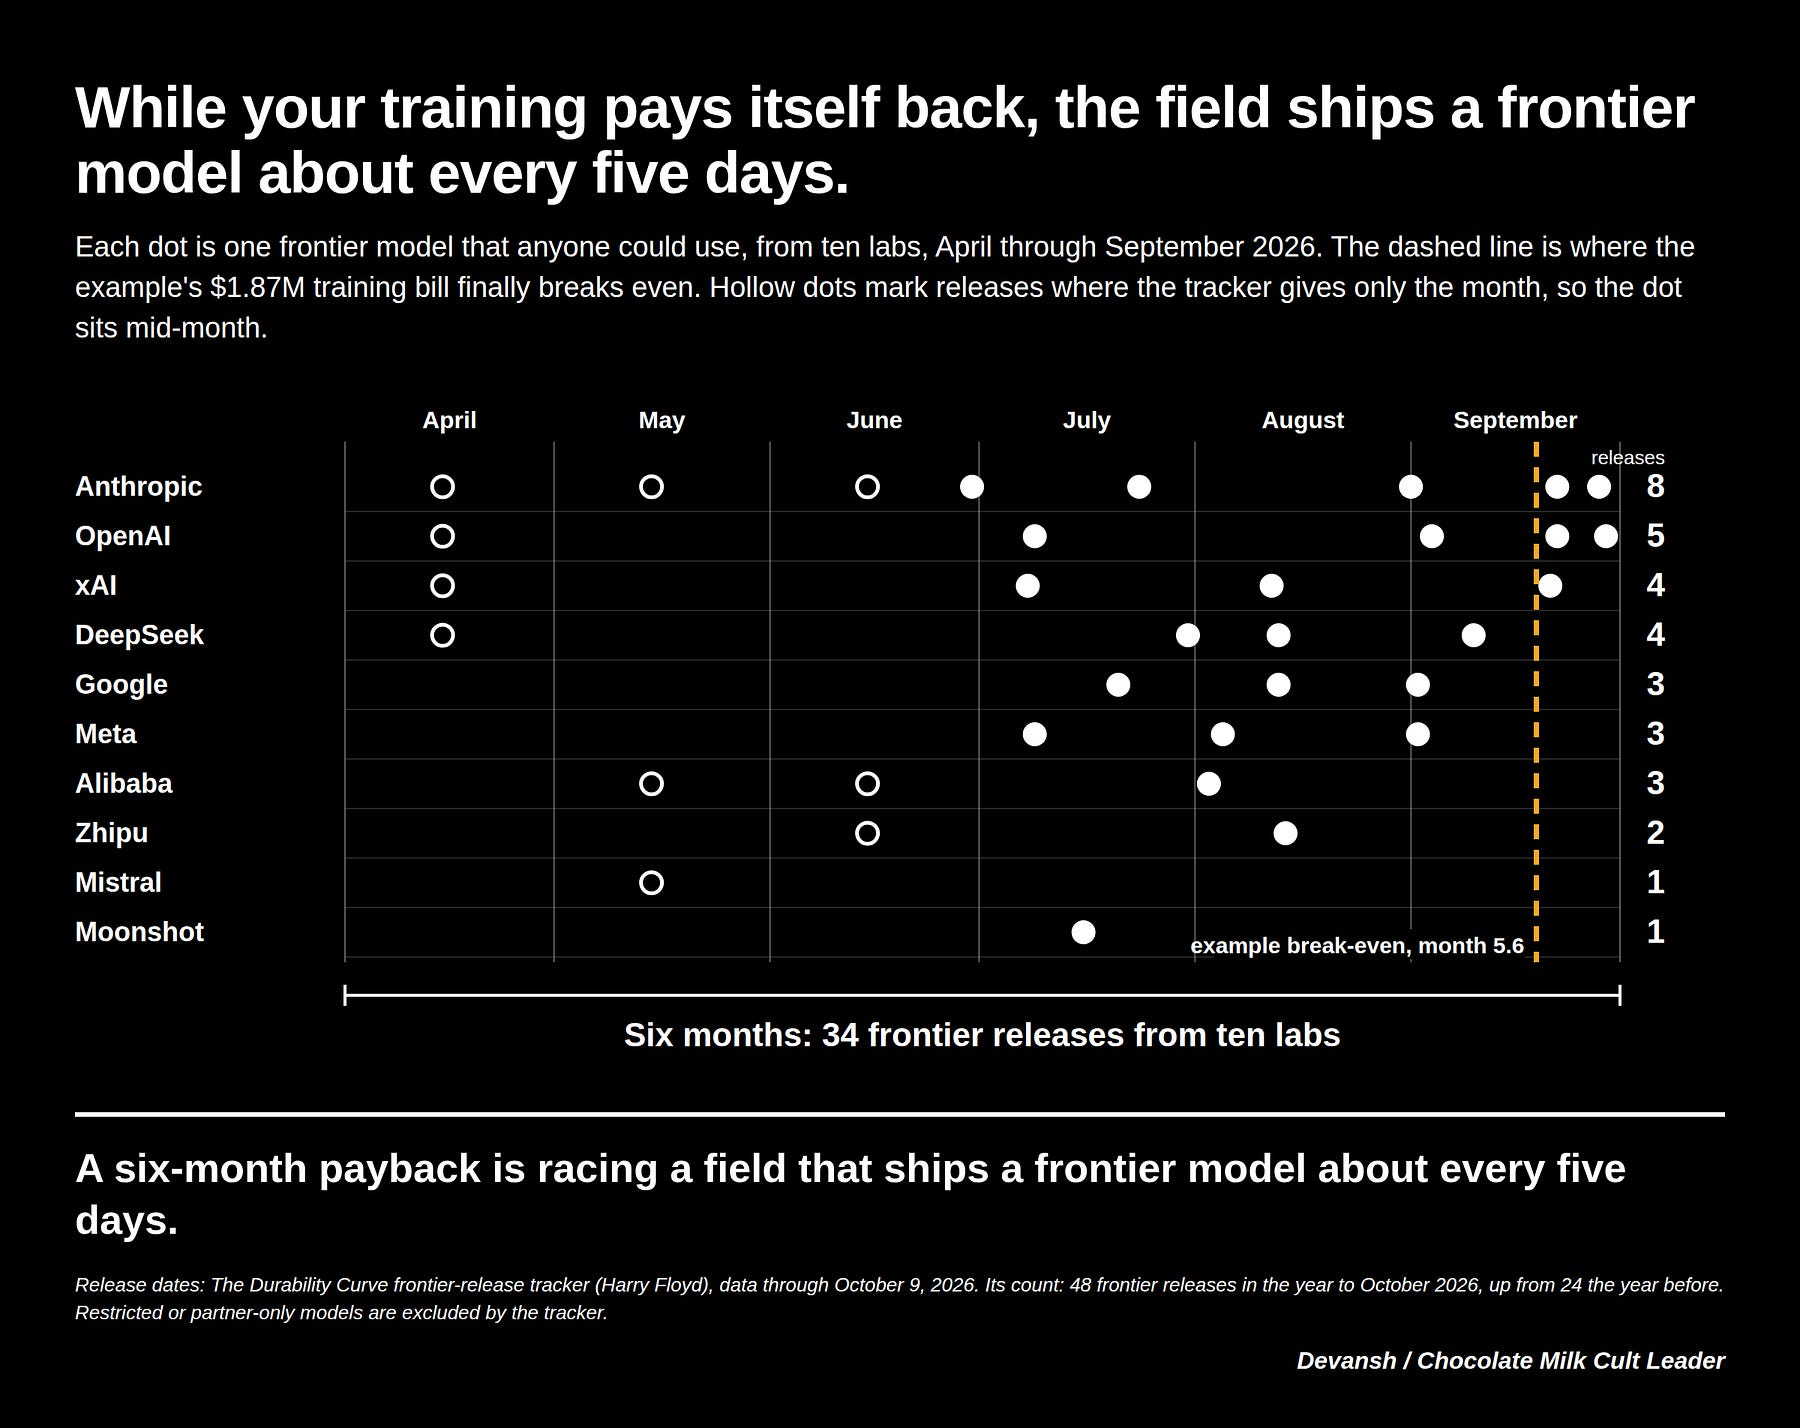
You STILL need ~6 months before your system produces ROI. Want to guess how often a new frontier (or close to frontier but more efficient) model is dropped?
It’s every 5 days. Best of luck of staying ahead of the most talent dense and well-funded ecosystem in tech across that many iterations.
You might think that this is the end of your woes, but life is rarely that kind to ones it chooses to beat down. Even if your newly post trained is somehow still coming out on top, that’s not going to last very long thanks to a nagging lil phenomenon in software called environment draft. Software changes. APIs change. Foundation models improve. And as you deploy more agents, those agents begin changing the workflows and software environments they’re operating within. So if your performance comes from training models to navigate a particular environment, you’re learning behaviors tied to a moving target. New tools, changed interfaces, and different workflows can force you to revisit that training.
Which means you start again. And again. And again.
And again.
And again.
Until you and Totenham Fans are the only people left at the heat death of the universe, both waiting to reach the promised land that never came
Now compare that against spending the same money improving your retrieval, memory, and execution infrastructure. Better infrastructure can compound across generations of foundation models. When a stronger model arrives, you can plug it into the existing system and immediately benefit from the engineering you’ve already paid for. You maintain that infrastructure, of course, but you aren’t rebuilding specialized model weights every time the underlying technology advances.
To reiterate, training can absolutely improve performance. But that isn’t the question that people actually care about. The question is whether that improvement justifies the money, maintenance, and opportunity cost. And that answer is almost always a no, especially in the many non-tech domains where the solution is sold. Even Cursor, which has some major structural advantages —
Operates in Coding, a more verifiable domain much closer to an AI researchers native domain expertise
Has a lot of money
Has a LOT of usage and traction.
Doesn’t have the AGI mandate and can focus on coding
still failed to push Composer to any meaningful difference compared to general models. So what secret do the other players in the space have?
This is a realization that most of the companies selling post training are slowly realizing. Which is why you’re seeing some goalposts being shifted, new terms being sold, and a whole new savior that will finally make domain specialized LLMs a reality.
Enter continous learning.
(Before I tear it apart, I want to differentiate between two things. As a researcher, I think CL is very interesting and has the potential to do some great things eventually. But for this article, our goal is to evaluate whether it’s ready to be sold in the short term, and that is a HELL NO).
3. Continual Learning: The Next Promised Land
The obvious problem with training models on company knowledge is that this knowledge keeps changing. Contracts get amended, regulations change, and workflows evolve. Constatly retraining models in the outdated ways is not sustainable. This is the impetus behind continual learning (CL): the field that studies how to keep updating the model with new information without destroying what it previously learned.
We would be very gung-ho about this field, except that updating knowledge is considerably harder than it sounds. A 2025 paper, The Mirage of Model Editing, found that knowledge-editing techniques reporting 96.8% success achieved just 38.5% under more realistic evaluations. Some earlier benchmarks had effectively leaked parts of the correct answers to models during testing. The methods also deteriorated dramatically after just 1,000 sequential edits.
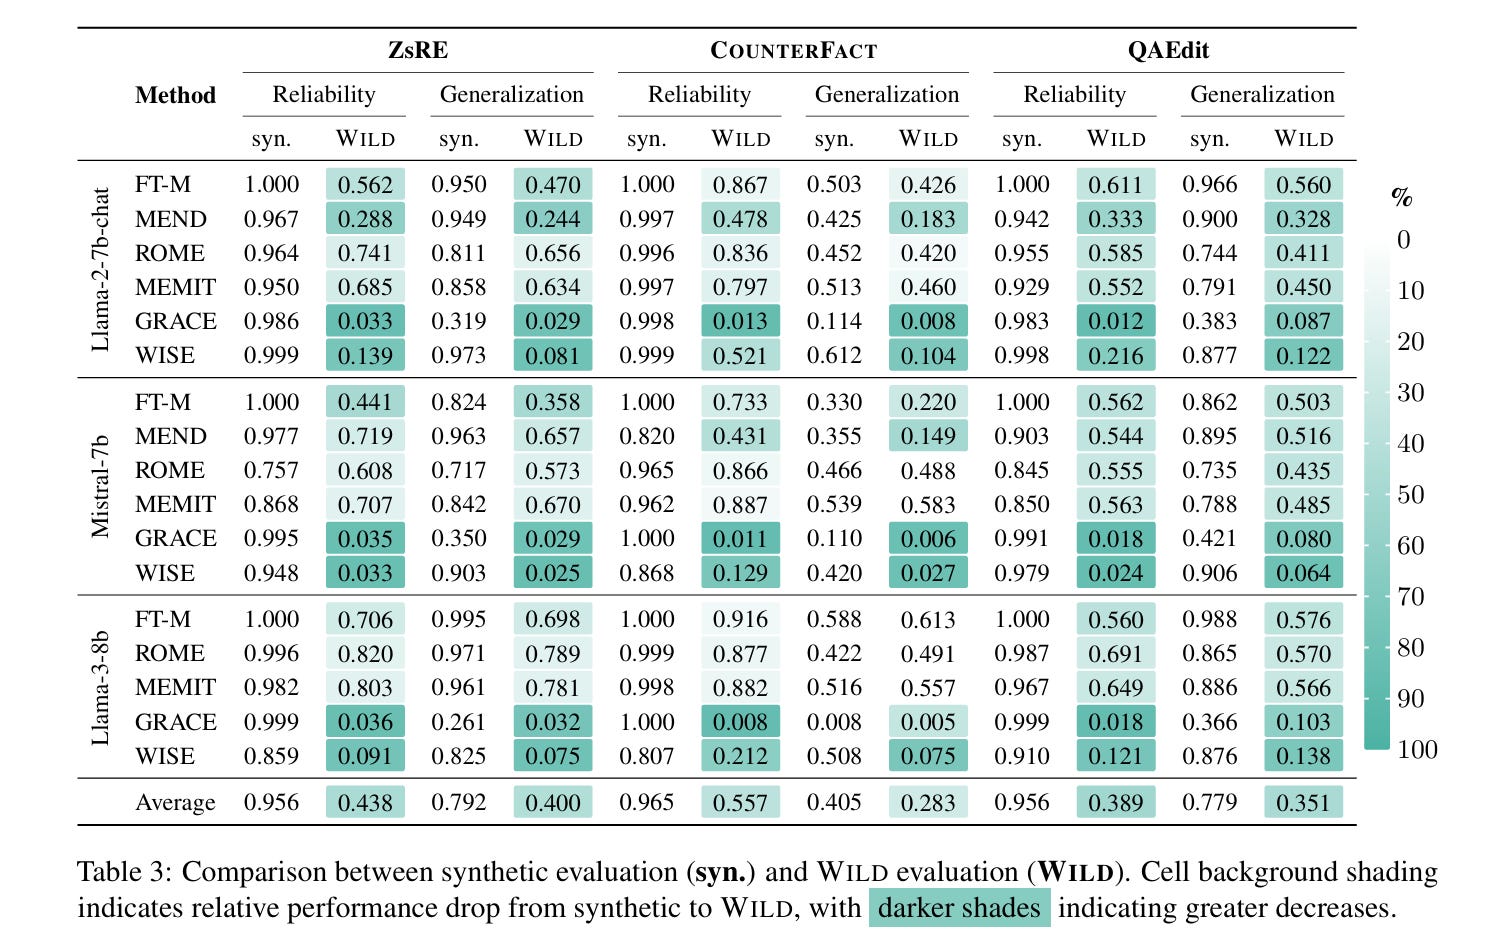
And that’s before dealing with how corporate information actually works. Change a contract’s payment terms, and you’ve potentially changed its obligations, financial exposure, and everything that depends on those terms. Getting the model to remember the new number doesn’t mean it’ll update all the conclusions built on the old one.
A 2026 ACL study examined exactly this problem with evolving real-world knowledge. Continual fine-tuning, knowledge editing, and ordinary RAG all struggled with temporal consistency. The researchers improved results by organizing external evidence into a time-aware knowledge graph.
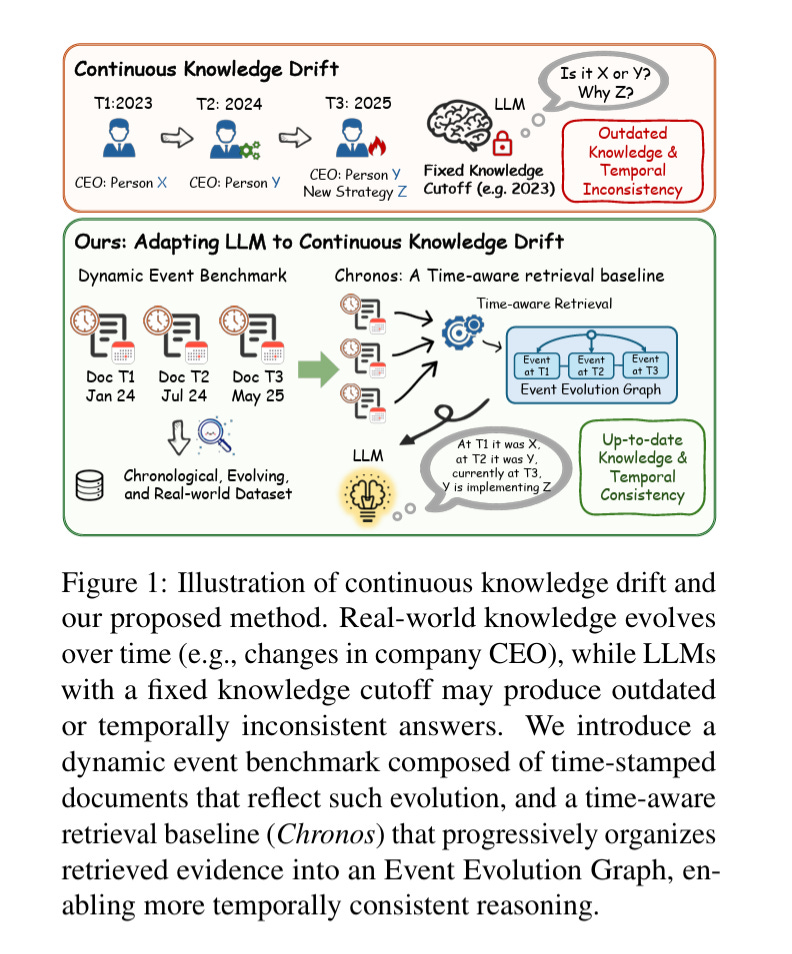
Notice what’s not needed? More training.
For the sake of argument, let’s say your vendor has the secret of continual learning (again a huge leap). Is there any utility to engaging with it then?
Each major refresh can mean preparing new training data, running experiments, evaluating what the model learned, checking what it forgot, and deploying another version. And you’re still paying the engineering team responsible for all of this. Let’s assume refreshing the model costs just 10% of the original $1.5 million GPU bill (this is really low if you look at the actual vendor claims, but we’re being generous here).
That’s $150,000 per update, or $1.8 million annually if you refresh monthly.
And you’re still quite susceptible to the generalization bias + environmental drift double whammy that hits normal training teams.
Compare that with maintaining knowledge externally. A contract changes? Update the record. A new regulation arrives? Update the knowledge base. Your reasoning system can access the latest information without another training cycle. Signals can be propogated more reliably (and most importantly you can detect every time they are not).
You still maintain and evaluate that infrastructure, but the investment can carry over to newer foundation models instead of remaining tied to one set of weights.
And once again, if any CL vendors have a problem with what I’m saying, let’s run a head to head publicly.
Conclusion: Don’t Train Your Own Model
There’s a rather beautiful business model hiding underneath all this. AI vendors get paid to train your models. Cloud providers get paid for the compute. Then everyone gets paid again when your data changes, your workflows evolve, or a better model comes along.
And somehow, you’re the one who’s supposed to be excited about this arrangement.
To reiterate what will undoubtely be deliberately misinterpreted about this article — I’m not saying that doesn’t work. I’m saying that for most (99%+) enterprise use cases, there are better and more efficient solutions out there. While commiting millions to your “own AI model” is a great way to get headlines and impress some board members, there’s honestly no good engineering or performance related reason to do so.
Your company’s knowledge doesn’t need to live inside a model’s weights. Your AI needs to know how to use it. That gets much easier with proper skills, documentation, and infra setup, especially as models get better with complex instruction following.
Perhaps we should try solving that problem before financing another GPU cluster.
Thank you for being here, and I hope you have a wonderful day,
Dev <3
If you liked this article and wish to share it, please refer to the following guidelines.
That is it for this piece. I appreciate your time. As always, if you’re interested in working with me or checking out my other work, my links will be at the end of this email/post. And if you found value in this write-up, I would appreciate you sharing it with more people. It is word-of-mouth referrals like yours that help me grow. The best way to share testimonials is to share articles and tag me in your post so I can see/share it.
I regularly share mini-updates on what I read on the Microblogging sites X(https://twitter.com/Machine01776819), Threads(https://www.threads.net/@iseethings404), and TikTok(https://www.tiktok.com/@devansh_ai_made_simple)- so follow me there if you’re interested in keeping up with my learnings.
Reach out to me
Use the links below to check out my other content, learn more about tutoring, reach out to me about projects, or just to say hi.
Small Snippets about Tech, AI and Machine Learning over here
AI Newsletter- https://artificialintelligencemadesimple.substack.com/
My grandma’s favorite Tech Newsletter- https://codinginterviewsmadesimple.substack.com/
My (imaginary) sister’s favorite MLOps Podcast-
Check out my other articles on Medium. :
https://machine-learning-made-simple.medium.com/
My YouTube: https://www.youtube.com/@ChocolateMilkCultLeader/
Reach out to me on LinkedIn. Let’s connect: https://www.linkedin.com/in/devansh-devansh-516004168/
My Instagram: https://www.instagram.com/iseethings404/
My Twitter: https://twitter.com/Machine01776819
While I agree that training your own model weight is a terrible idea, I need to point out a false assumption.
“There just is no way to reliably inject knowledge in the weights of already trained LLMs”
I developed an inference engine that uses a sparse auto encoder to identify and classify clusters in a model’s activation forest. I use this to detect a lack of knowledge for a given domain using a small classifier model to graft virtual knowledge domains when the backbone model doesn’t have the knowledge required to respond. I developed this in an effort to increase intelligence in small models for robots. Robots need small models for speed, but need to be savants for specific knowledge domains. I additionally added a second way using LoRa to graft knowledge domains on the fly as well.
The good news is that it works. The bad news is while it adds knowledge, it does not add reasoning. To increase a model’s intelligence, you need more layers.
More importantly, I learned exactly how hard and expensive it is to even train a single knowledgeable domain.
RAG and harness engineering are the shortest path to what most organizations can get a cost effective benefit.
If post-training doesn't work that well, could companies do midtraining on an already pretrained base model? I think cursor did something like that (before getting acquired by grok)